The World Will Store 200 Zettabytes Of Data By 2025 - Cybercrime Magazine
Executive brief
A Cybercrime Magazine headline projected that the world would store 200 zettabytes of data by 2025. The scale is difficult to visualize. One zettabyte equals one sextillion bytes, or 10²¹ bytes. Yet the strategic issue is not the size of the number alone.
The real issue is what persistent data growth does to enterprise risk, infrastructure, capital allocation, governance, and operating discipline.
A projection is not the same as a verified measurement. “Data created,” “data generated,” “data stored,” and “storage capacity” are different categories. Leaders should validate the original reporting, underlying methodology, publication date, scope, and primary source before relying on the figure in a consequential decision.
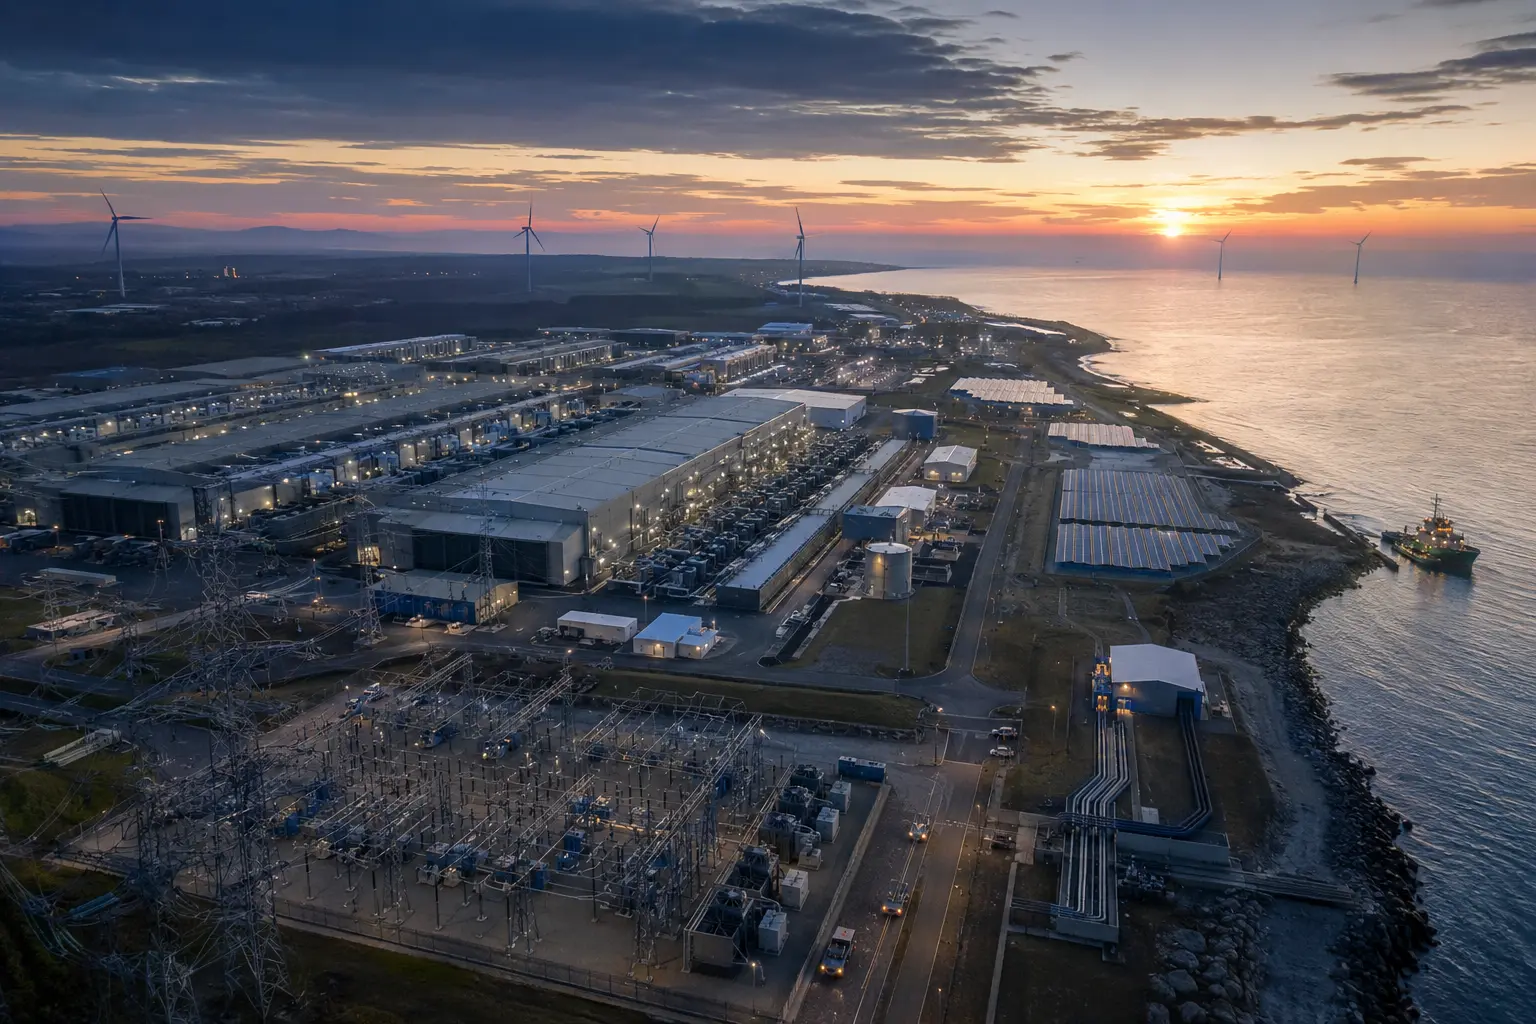
Even with that caution, the direction is clear. Organizations are creating, collecting, copying, processing, and retaining more data across more environments. Cloud platforms, connected devices, artificial intelligence, digital services, software telemetry, video, industrial systems, backups, and regulatory requirements all add to the burden.
More data can produce greater insight. It can also create more exposure.
The executive mandate is therefore not to store everything. It is to determine what data creates value, what data creates obligation, what must be protected, what should be deleted, and what infrastructure can sustain the resulting workload.
The order matters.
Govern first. Architect second. Procure third. Measure continuously.
What happened
Cybercrime Magazine published a headline stating that the world would store 200 zettabytes of data by 2025. The supplied source is a Google News link directing readers to current coverage.
The headline presents a forecast rather than, on the information supplied, a confirmed final measurement. That distinction is important. Forecasts can be useful for scenario planning, but their value depends on definitions and assumptions.
Decision-makers should establish:
- Whether the figure refers to data stored at a specific point in time or data generated over a period
- Whether duplicate data, backups, replicas, caches, and transient files are included
- Whether the estimate covers enterprise systems, consumer devices, public cloud infrastructure, edge environments, or all categories combined
- Whether the number represents installed storage capacity, usable capacity, or actual occupied storage
- Whether the projection was produced by Cybercrime Magazine or cited from another research organization
- Whether the estimate has since been revised, validated, or superseded
These are not academic distinctions. They can materially change the interpretation of the number.
A backup copy may increase stored volume without creating a new business record. A replicated database may improve resilience while multiplying storage consumption. Video surveillance may generate enormous files while producing only a small amount of decision-relevant information. Artificial intelligence may require multiple versions of training data, derived datasets, model artifacts, embeddings, logs, and evaluation records.
The headline is therefore best read as a signal about scale, not as a complete basis for action.
Read for decisions, not noise.
Why it matters
Data growth changes the economics and risk profile of nearly every digital organization.
The first consequence is infrastructure pressure. Larger data estates require more storage, network capacity, backup capability, recovery planning, observability, and administrative control. Moving data between systems may become as consequential as storing it. Latency, bandwidth, data locality, and transfer charges can constrain otherwise attractive technology strategies.
The second consequence is security exposure. Data cannot be stolen, corrupted, encrypted, or leaked if the organization no longer holds it. Every unnecessary record can become an unmanaged liability. Every additional repository can create another identity boundary, access-control problem, configuration risk, or recovery dependency.
The third consequence is governance complexity. Organizations must know what information they possess, where it resides, who owns it, who can access it, how long it must be retained, and when it should be destroyed. Without a reliable inventory, leaders cannot make defensible claims about privacy, security, regulatory compliance, litigation readiness, or artificial intelligence governance.
The fourth consequence is financial. Storage prices may decline on a unit basis while total costs continue to rise. The full cost is not limited to disks or cloud capacity. It includes ingestion, replication, transfer, backup, recovery, encryption, monitoring, licensing, labor, compliance, and eventual deletion.
Cheap storage can encourage expensive indiscipline.
The fifth consequence is strategic. Data can strengthen forecasting, personalization, automation, research, public service delivery, operational control, and investment analysis. But volume does not guarantee value. Poorly labeled, duplicated, stale, biased, or inaccessible information can slow decisions and weaken models.
For artificial intelligence in particular, data quality, provenance, permissions, representativeness, and lineage often matter more than raw volume. A large dataset with uncertain rights or weak controls may be unusable. A smaller, governed dataset may deliver greater operational value.
Strategic implications
Leaders should examine this issue through five connected lenses.
1. Value
Not all data deserves equal treatment. Organizations need a classification model that distinguishes critical records, operational data, analytical assets, regulated information, intellectual property, temporary files, and redundant or obsolete material.
Value should be tied to a use case. If the organization cannot identify the decision, service, control, or obligation supported by a dataset, continued retention deserves scrutiny.
2. Risk
Data risk grows through concentration and sprawl.
Concentration creates attractive targets and systemic dependencies. Sprawl makes information difficult to discover, classify, secure, and delete. A sound architecture must balance availability with segmentation, resilience with simplicity, and access with control.
Cybersecurity planning should assume that some systems will fail or be compromised. The practical question is whether the organization can contain the event, maintain essential functions, restore trusted information, and explain what occurred.
3. Economics
The correct measure is total lifecycle cost per useful unit of data, not the advertised price per gigabyte.
Leaders should account for:
- Primary storage
- Backup and replication
- Network movement and cloud egress
- Security and monitoring
- Data engineering and administration
- Compliance and legal review
- Business continuity and recovery testing
- Archiving and defensible deletion
A low acquisition price can conceal a high operating burden. Vendor dependence may also increase when data volumes become too large, too interconnected, or too expensive to migrate.
4. Architecture
The central architectural decision is not simply cloud versus on-premises infrastructure. Most organizations operate across multiple environments.
The stronger question is where each type of data should reside and why.
Placement should reflect sensitivity, latency, availability, sovereignty, integration, recovery objectives, workload characteristics, and cost. Some data belongs close to the point of use. Some requires centralized governance. Some should move into low-cost archival tiers. Some should never have been retained.
5. Accountability
Data governance fails when everyone participates but no one owns the result.
Executive leadership should establish clear accountability for:
- Data ownership
- Classification standards
- Access approval
- Retention and deletion
- Backup integrity
- Recovery performance
- Third-party handling
- Regulatory obligations
- Artificial intelligence use
Technology teams can administer controls. They cannot unilaterally decide the legal, ethical, operational, and economic value of every dataset. Business, legal, security, records, risk, and technical leaders must share the work without blurring accountability.
What leaders should do now
Begin with a decision-oriented data review.
First, verify the external claim. Locate the original Cybercrime Magazine article, identify any underlying research, compare definitions, and check whether later evidence supports the projection. Do not build a board presentation or capital plan around an unexamined headline.
Second, create or refresh the enterprise data inventory. The inventory should identify major repositories, owners, classifications, geographic locations, critical dependencies, retention requirements, and access models. Perfection is not required before action begins, but unknown systems must be treated as risk.
Third, rank data by business criticality and sensitivity. A practical model can use four categories:
- Mission-critical and highly sensitive
- Operationally important
- Useful but replaceable
- Redundant, obsolete, or trivial
Each category should have defined requirements for protection, availability, backup, recovery, retention, and disposal.
Fourth, test recoverability. A successful backup job is not proof of successful recovery. Leaders should ask whether systems can be restored within required timeframes, whether restored data can be trusted, and whether dependencies have been tested under realistic conditions.
Fifth, control retention. Legal holds and regulatory requirements must be respected, but “keep everything forever” is not a mature policy. Retention schedules should be documented, approved, technically enforceable, and subject to exception management.
Sixth, connect artificial intelligence plans to data governance. Before expanding AI use, confirm provenance, permissions, quality, security, lineage, and acceptable use. Model performance cannot compensate for unlawful access, weak data rights, or unreliable source material.
Seventh, measure outcomes. Useful indicators include:
- Growth in storage by business unit and data class
- Percentage of repositories with accountable owners
- Percentage of data classified under approved policy
- Recovery time achieved during testing
- Volume of redundant or obsolete data removed
- Number of privileged accounts with data access
- Cost by storage tier and workload
- Exceptions to retention and deletion policy
These measures turn an abstract global trend into an operational management system.
The Poe Perspective
Leaders should not confuse the speed of a headline with the depth of a decision.
The useful question is not simply what changed. It is what the change means for people, capital, infrastructure, execution, and the next credible move. This is where disciplined strategy begins.
The 200-zettabyte projection may prove accurate, high, low, or differently defined than a casual reading suggests. The executive responsibility remains the same: distinguish signal from certainty and convert the signal into disciplined preparation.
More data is not automatically more knowledge.
More storage is not automatically more resilience.
More access is not automatically more capability.
The strongest organizations will not be those that accumulate the most information. They will be those that know what they hold, why they hold it, how it creates value, how it can cause harm, and when it should be removed.
Complex ideas. Clear direction. Real movement.
Strategy must survive contact with reality. That means tested recovery, enforceable policies, funded controls, named owners, credible metrics, and architecture aligned with actual operating needs.
Questions decision-makers should ask
- What primary source supports the 200-zettabyte projection, and what exactly does it measure?
- How quickly is our own data estate growing, and which activities are driving that growth?
- Which datasets directly support revenue, public value, operational continuity, compliance, or strategic differentiation?
- Where do we retain information without a defined owner or purpose?
- What would create the greatest damage if exposed, corrupted, unavailable, or manipulated?
- Can we restore critical systems from trusted backups within approved recovery objectives?
- Are our retention rules legally defensible and technically enforced?
- How much of our storage cost comes from duplication, replication, transfer, and unmanaged growth?
- Could vendor lock-in limit our ability to migrate, negotiate, or modernize?
- Are AI systems using data with verified provenance, permissions, quality, and lineage?
- Which executive owns the enterprise result rather than one technical component?
- What must be decided in the next 30, 60, and 90 days?
Move from insight to implementation
PoeTech Global Consulting can structure a focused strategic consultation around data growth, cyber resilience, infrastructure economics, and governance.
The consultation should begin with the decision at hand: a cloud migration, AI initiative, storage modernization, resilience program, governance redesign, investment review, or public-sector digital strategy. From there, the work can assess the organization’s present state, identify material gaps, clarify tradeoffs, and define a sequenced action plan.
A focused engagement may examine:
- Data inventory and ownership
- Classification and retention controls
- Infrastructure and cloud architecture
- Cybersecurity exposure
- Backup and recovery readiness
- AI data governance
- Cost drivers and vendor dependence
- Executive accountability and performance measures
The objective is not a larger report. It is a clearer decision, a defensible operating model, and an executable next move.
Source notes
Source: Current coverage
Cybercrime Magazine headline: “The World Will Store 200 Zettabytes Of Data By 2025”
The supplied link is a Google News redirect. Decision-makers should review the original article and any primary research it cites before using the projection in a consequential decision.
About the author
Rev. Dr. Gerald F. Poe Jr.
Founder and Chief Executive Consultant of PoeTech Global Consulting. Technologist, strategist, veteran, aviator, and cross-sector advisor with more than three decades of experience spanning AI, energy, sustainable data centers, telecommunications, UAS, healthcare innovation, public infrastructure, and venture development.